
Most organizations sitting on a large video archive have the same complaint: the content is good, and nobody watches it. The usual diagnosis is that the recommendations are poor. The usual reality is that there is nothing for a recommendation engine to work with.
What a video file knows about itself
Almost nothing. A file arrives with a filename, a duration, a resolution and a date. If somebody typed a title and a synopsis at the point of upload, there is a title and a synopsis. Everything else a viewer might search for — who is in it, what it is about, what happens in it, what was said — exists only as pixels and audio.
Search, recommendation, related content, editorial rows and accessibility all run on metadata. None of them can run on pixels.
Free guide
OTT Platform Growth & Monetization Guide
The benchmarks, formulas and ROI scenarios behind a profitable streaming platform. Thirty slides, free.
Why the backlog never gets written
Because writing it is unpaid work with no deadline. Tagging a thousand hours of archive is a project nobody has budget for, which competes against publishing this week’s content, which has an audience waiting. The backlog therefore grows at exactly the rate the library does.
Any plan that depends on catching up by hand has already failed. The only version that works is one where new material arrives already described, so the backlog stops growing, and the historic material is processed in the background rather than by a team.
Describing on ingest
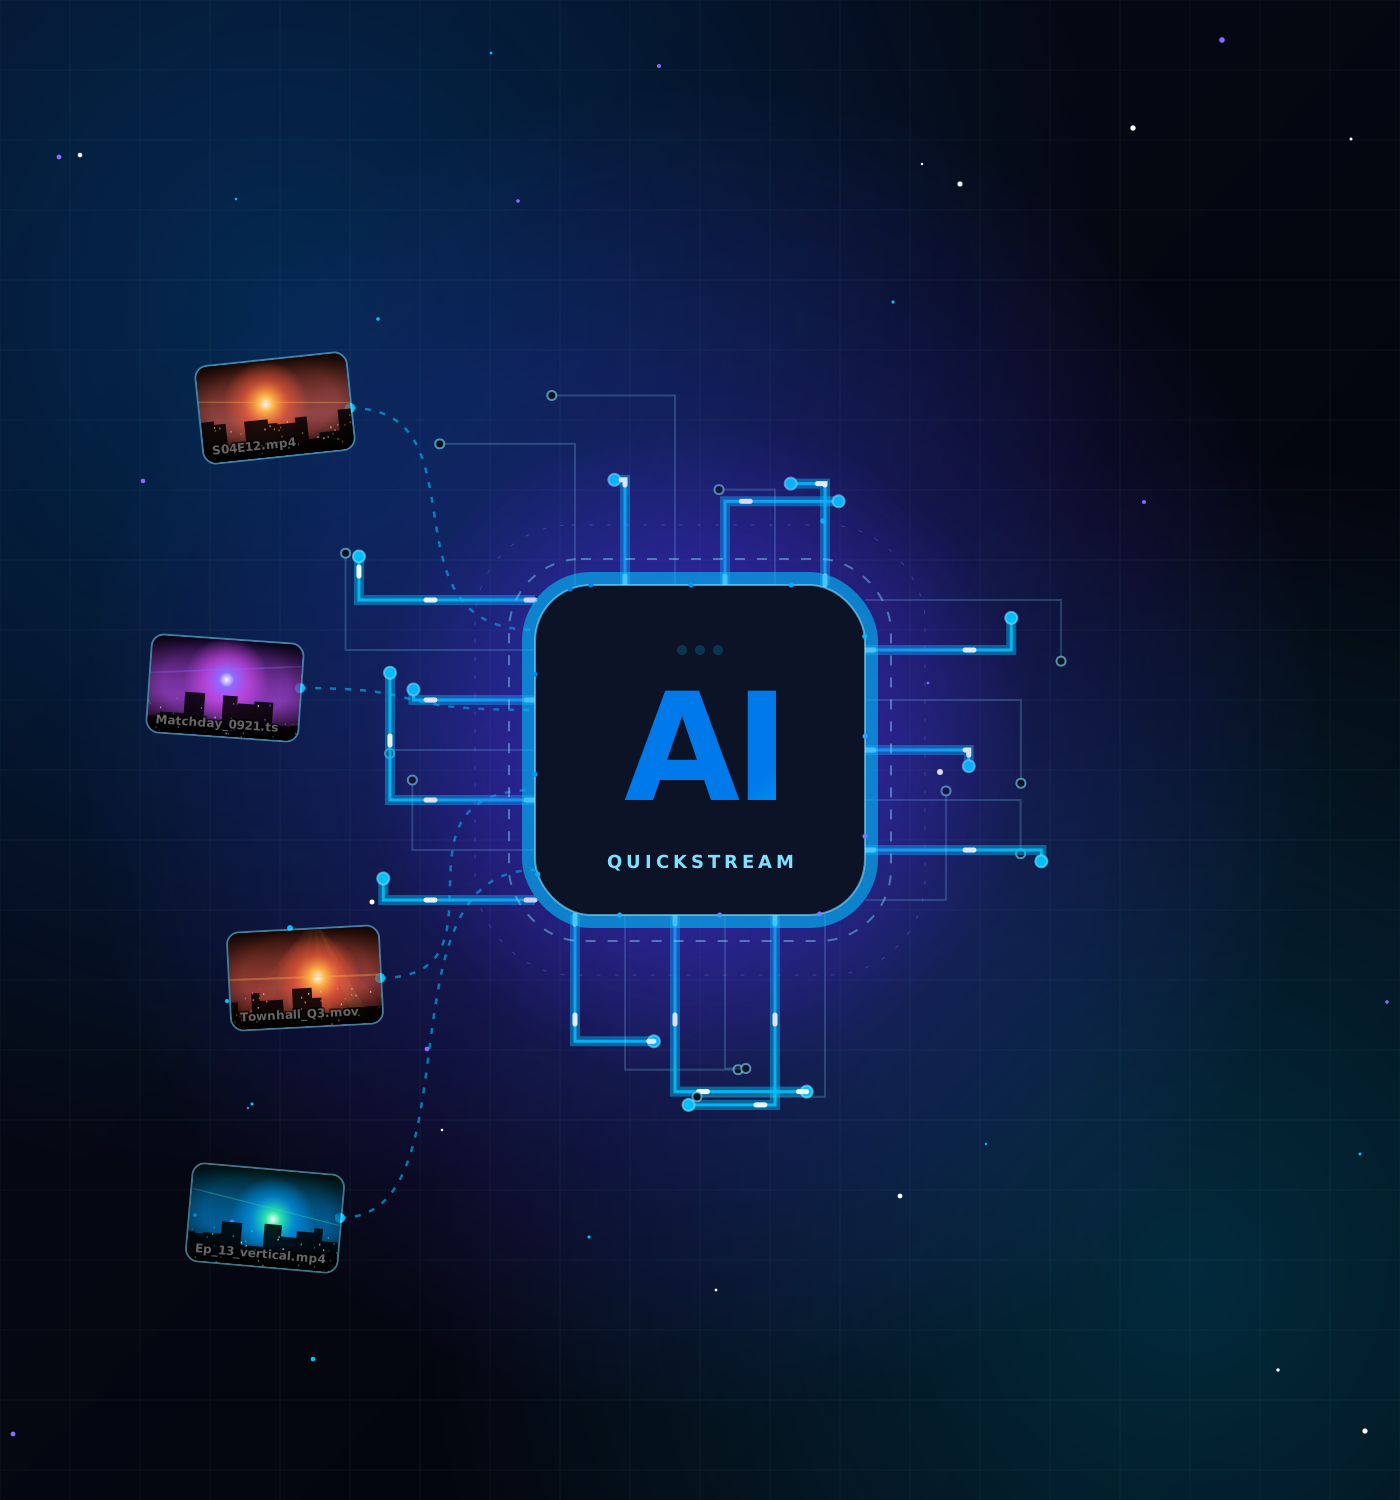
The practical answer is to make description part of the upload rather than a task that follows it. As an asset arrives it is transcribed, the transcript is used to produce a summary and a set of topics, people and objects on screen are identified, and captions are generated from the same transcript.
None of this is a substitute for an editor who knows the catalog. It is a substitute for an empty field. An editor correcting a generated synopsis is doing five minutes of work; an editor writing one from scratch for eight hundred titles is doing a job nobody will finish.
What changes when it is there
- Search stops being title-only. A viewer can find the episode by what was said in it.
- Related content has something to relate on beyond “same series”.
- Editorial rows can be assembled from the catalog rather than from memory.
- Captions exist, which is an obligation in more places every year and a discovery advantage everywhere.
The archive was always worth something. Metadata is what makes it findable, and findable is what makes it worth something to somebody other than you.